Qiang (Nate) Zhang

Speech LLM Engineer · Supervised Fine-Tuning

I work on supervised fine-tuning (SFT) for speech interaction at iFLYTEK. My focus is training data and fine-tuning: making responses more natural while preserving reasoning and general capabilities.

Previously, I studied Computer Technology at Tianjin University, where my research focused on image restoration and fusion. Before that, I studied Data Science and Big Data Technology at Anhui University.

An orange fox sailing a book-shaped boat beneath a star

Start here

The SFT and ASR experiments are small independent studies using open models and public or synthetic data. The SFT study is text-only; its results do not establish general capability retention or speech quality.

Research

IJCAI 2026

Interactive All-in-One Image Restoration and Fusion

Bing Cao, Qiang Zhang†, Xingxin Xu, Pengfei Zhu

† First student author

International Joint Conference on Artificial Intelligence, 2026

Restoring degraded images and fusing infrared and visible information with text instructions and a pretrained diffusion model.

Paper, figures and citation are public. Implementation and model weights are not publicly available.

About this work

AIR-Fusion adapts a frozen diffusion model for infrared–visible image fusion under degradations such as noise, haze and low light. It aligns infrared information and text instructions with the model, then constrains the denoising process to preserve source-image structure and detail.

Cite this paper
@inproceedings{ijcai2026p105,
  title = {Interactive All-in-One Image Restoration and Fusion},
  author = {Cao, Bing and Zhang, Qiang and Xu, Xingxin and Zhu, Pengfei},
  booktitle = {Proceedings of the Thirty-Fifth International Joint
               Conference on Artificial Intelligence, IJCAI-26},
  pages = {935--943},
  year = {2026},
  doi = {10.24963/ijcai.2026/105}
}
Personal projects

SFT training targets and question rewording

Qwen2.5-0.5B / LoRA / Reproducible experiment

A small text-only study with 96 synthetic training examples, two answer targets and two seeds. The follow-up tests alternate question wording and reports final numeric answers separately from output format.

Training code, fixed inputs, raw responses and scoring decisions are public. The reports discuss the unequal supervision budgets and the limits of the results.

A separate 2026-10-04 grouped-condition run uses 45 synthetic training questions and reports all five conditions on shared dev/test sets, with final-number matches, strict format measures and unequal supervision budgets kept explicit.

SFT Rewrite Checker

JavaScript / Training data review / Runs in your browser

Compare the complete input, original answer and rewritten answer. Simple rules surface changes in numbers, condition cues, certainty, clarification requests and formatting for human review.

Import JSON or JSONL, filter the review queue, and export decisions with notes. The tool keeps data in the current page and does not call a model or upload records.

Speech evaluation pipeline from input validation to metrics, diagnostics, and reports
Evaluation pipeline · view full diagram

Speech Evaluation Demo

Python / SQLite / Speech evaluation

A small personal project for comparing reference transcripts with recognition outputs. It calculates character error rate and shows the insertions, deletions and substitutions behind each score.

Compare two transcript versions on the same references, filter regressions, and inspect character edits. Includes synthetic examples and local CSV import.

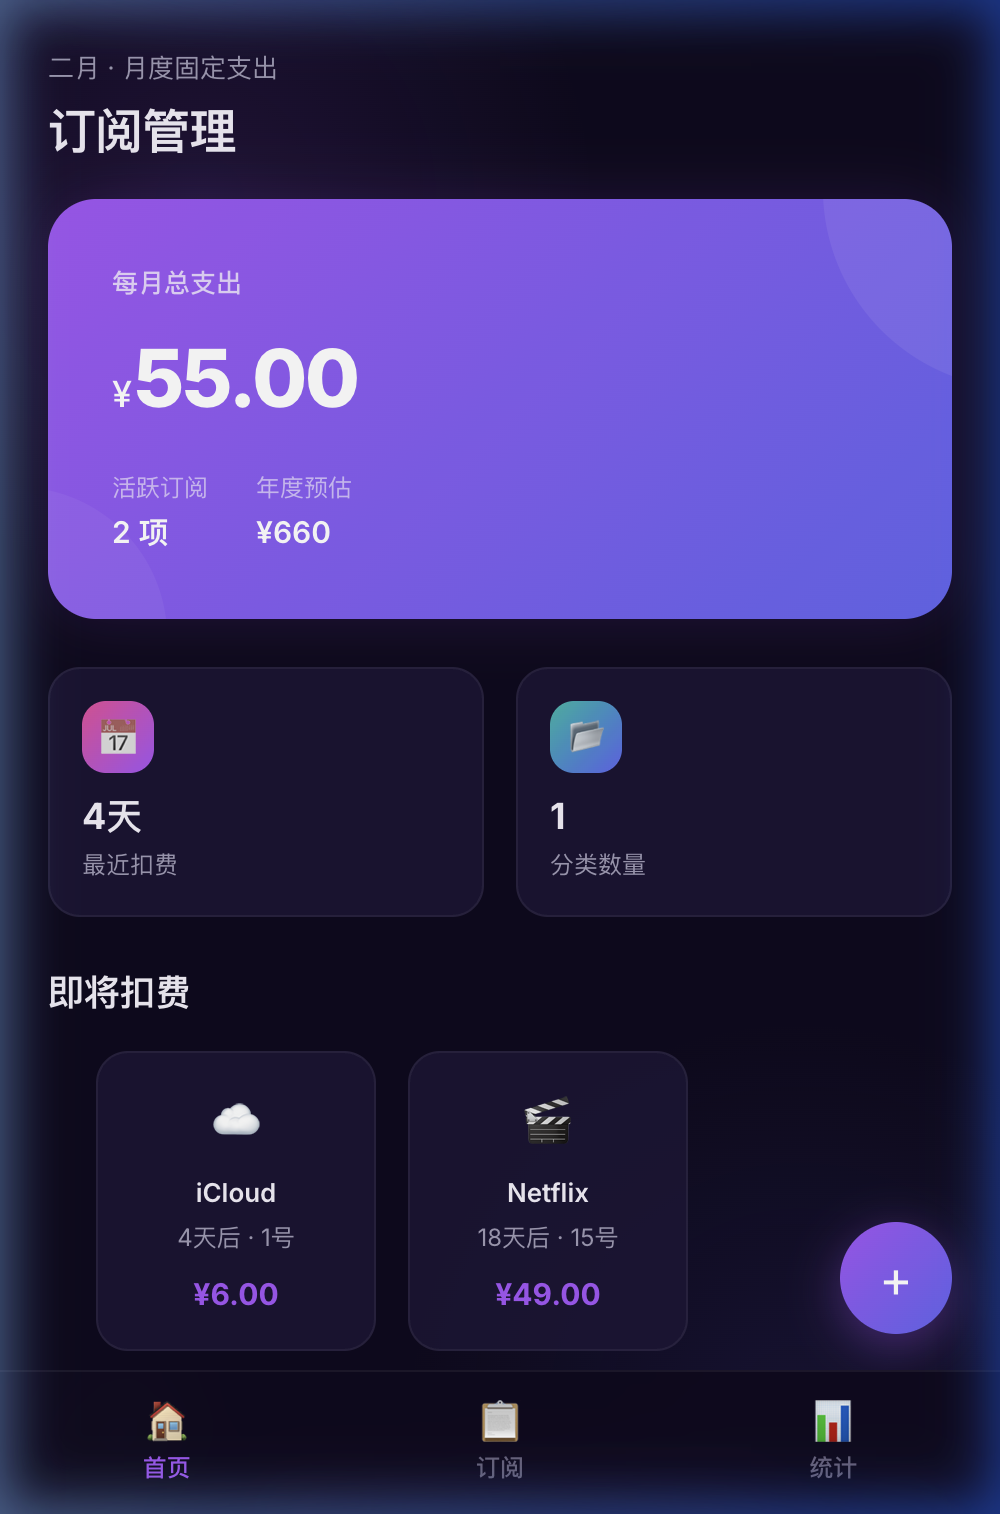
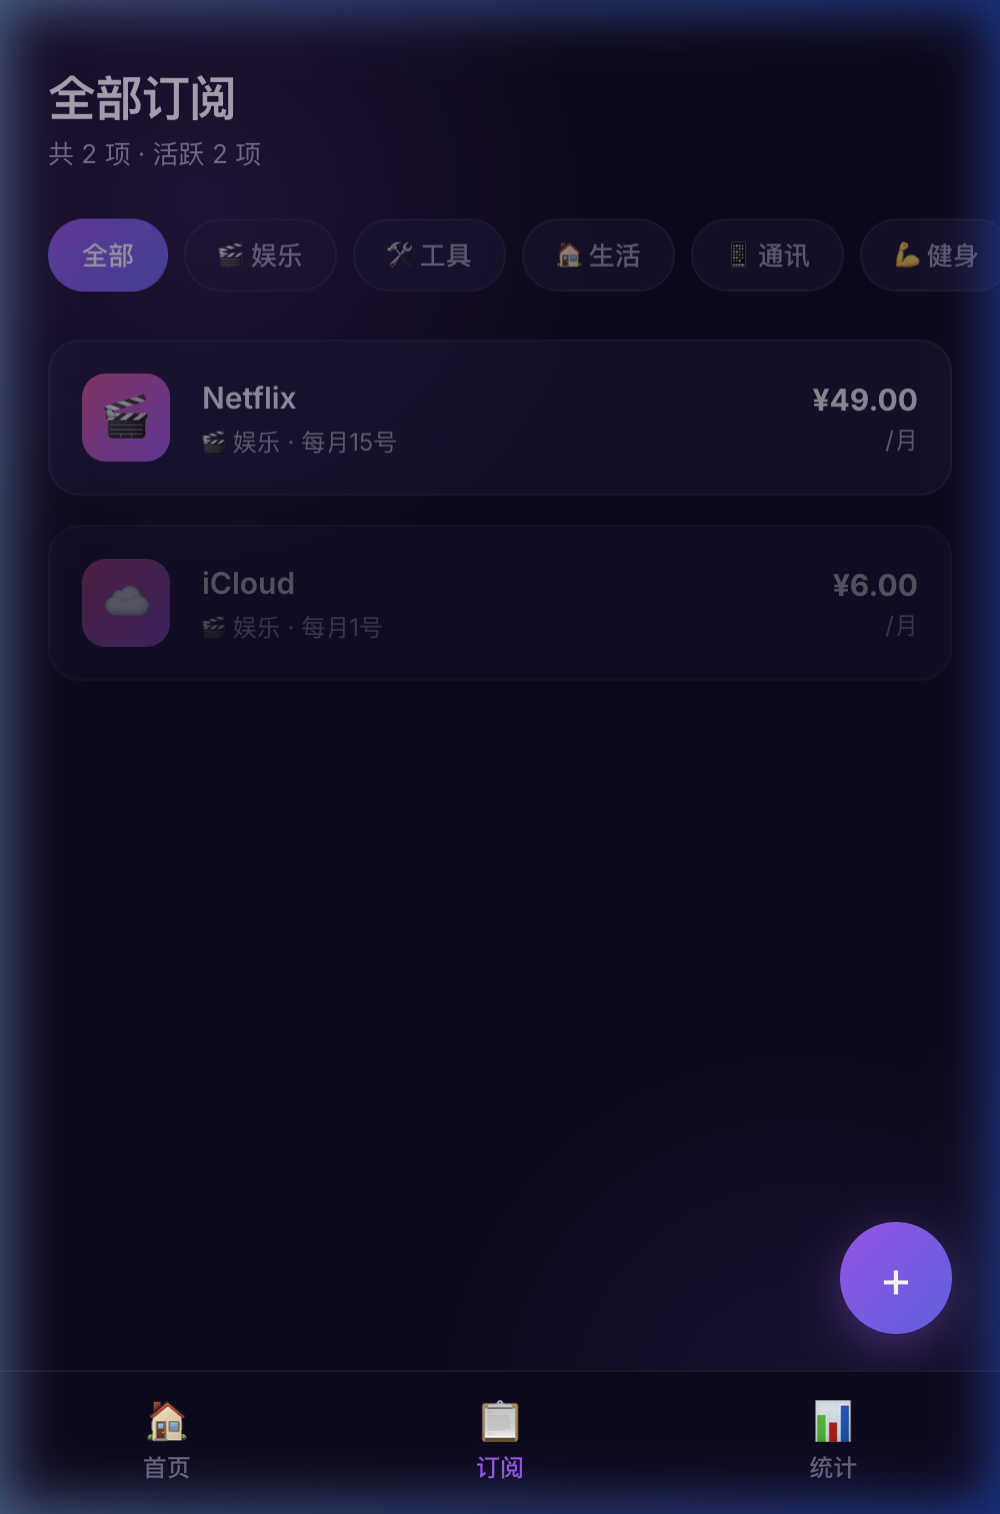
SubTracker dashboard screenshotSubTracker subscription list screenshot
Dashboard and subscription list

SubTracker

JavaScript / IndexedDB / Progressive web app

A subscription tracker with monthly totals and renewal dates. Data stays in your browser, and the app works offline.

Technical writing

RSS · Follow the technical notes in your feed reader. No signup needed.

I write in Chinese about model training, evaluation and my research. Also on Zhihu ↗.

LLM evaluation · Q&A · 中文

如何评估 LLM?

同样是 60% 的正确率,模型可能错在完全不同的题上。

Background

Contact

zhangqiang_c@outlook.com